How to create a business continuity plan
When staff can't access email, the business system crashes, or ransomware is suspected, it doesn't matter how good the technology was yesterday. What matters is whether people know exactly what to do for the next few hours. The question of how to create a disaster recovery plan is therefore not just about documents and backups, but about keeping the business operational when it matters.
For small and medium-sized businesses, a short operational disruption can have unpleasantly large consequences. Revenue is delayed, service deteriorates, staff waste time finding temporary solutions, and customer trust is damaged. A well-prepared disaster recovery plan turns uncertainty into clear task allocation. It helps managers make informed decisions and the IT team restore systems in the correct order.
How to create a disaster recovery plan that works in practice
A common mistake is to write a general document stating that "managers should be informed" or "backups should be restored." Such a document is of little help when systems are down on a Friday afternoon. A disaster recovery plan needs to answer simple but challenging questions: What events can stop operations? Who decides the next steps? Which systems need to be recovered first? Where are the secure backups and how do we verify that they work?
Start with the business, not the technology. Record what services the company needs to be able to provide, what information is necessary for this, and what systems support that work. A company that relies on a booking system has a different prioritisation problem than a company where drawings, contracts, or production data are most important. The goal is not to restore everything at once. The goal is to get the most critical part of the business up and running within an acceptable timeframe.
Set two criteria for each critical system. Firstly, the maximum allowable downtime, for example, four hours or one working day. Secondly, how much data loss is acceptable, for example, data from the last hour or the last 24 hours. These criteria are often called recovery time and recovery point, but managers don't need technical terms to make the decision. They need to decide what the business can tolerate.
Map likely disruptions
A disaster recovery plan doesn't need to be based on the most unlikely catastrophes. It should address events that businesses actually experience: cyber-attacks, cloud service failures, employee errors, power outages, equipment theft, network equipment failure, or fire and water damage. Some disruptions are localised, others affect the entire environment.
It is useful to categorise incidents by impact rather than writing a separate plan for each possibility. For example, one response path is needed when a single device or user is attacked, but another when shared file areas, authentications, or emails fail. The plan then becomes shorter, clearer, and easier to use.
For each incident, it must be defined what constitutes a confirmed problem and when it becomes an emergency. Suspicious email is not necessarily a disaster for operations. Encrypted shared data, unusual logins, or systems inaccessible to many employees, however, call for immediate action. Clear boundaries reduce the risk of people waiting too long for approval.
Define responsibilities before they become urgent
In an emergency, no one should have to look for a phone number, wonder who can shut down a system, or ask who should talk to customers. Name responsible parties with roles and deputies. There must be an operations manager who assesses the impact on business, a technical manager who directs isolation and recovery, a communications manager who handles coordinated messages, and a director who can approve costs or operational decisions.
Keep contact lists outside the systems that might fail. This can be a printed copy in a locked cabinet and accessible, or a protected copy in a secure mobile solution. The list should include key phone numbers, contacts at the internet provider, insurance company, lawyer if applicable, bank contact, and external technical support. Review it regularly, especially after staff changes.
Communications must also be predetermined. Staff need to know where to turn, customers need honest information without unconfirmed promises, and managers need status reports at regular intervals. Short messages like 'We are investigating the disruption, the next update will be at 2 PM' are usually better than silence or speculation.
Protect the data, but also test the recovery
Backups are the core of many emergency plans, but a backup alone is not a guarantee. If the backup is connected to the same environment and is attacked, if it is insufficient, or if no one has tested recovery from it, the company may discover the problem when it is too late.
A good backup strategy has more than one backup, keeps at least one backup separate from the daily operating environment, and protects it against unauthorised changes. Furthermore, it must be decided what is backed up. Business systems, file areas, and emails are obvious components, but configurations, access rights, network equipment settings, and key documents can be just as important for rapid recovery.
Test recovery regularly. Choose a scenario that resembles real-world conditions, such as recovering a single critical folder, virtual machine, or user data in an isolated environment. Measure the time, verify that the data opens correctly, and record what slowed down the process. Testing may reveal that the backups are fine, but passwords, permissions, or priorities are missing. These are good news when they arrive on a normal working day.
Build a response to cyberattacks
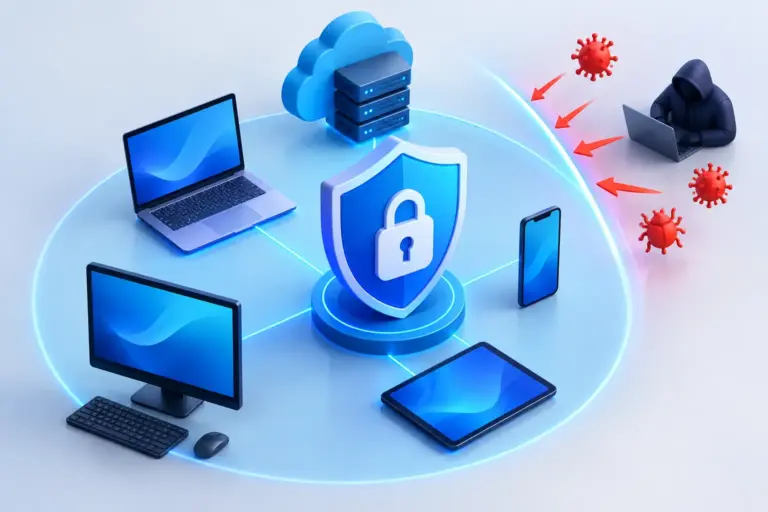
A cyberattack often requires a different approach than a traditional system failure. The first task is not always to get the system running again, but to stop the spread. A device showing signs of infection may need to be disconnected from the network immediately, but not turned off unless a technical manager advises it. A turned-off device can make investigation and evidence collection more difficult.
The plan should clearly state who can disconnect devices, who will block user access, how suspicious incidents are recorded, and when an insurance company or relevant authorities need to be notified. Companies working with personal data or sensitive customer data also need a process to assess potential data breaches and notification obligations.
Security monitoring, multi-factor authentication, password management, and regular updates reduce the likelihood of a serious incident. However, they do not replace an emergency plan. No defence is perfect, and the cost of a poor response can be greater than the cost of preventative work.
Make the plan usable, not just approved
Write the instructions with the expectation that a tired employee can follow them under pressure. Use simple language, short steps, and clear decision points. Technical information, such as installation guides or specific recovery commands, can be in appendices accessible only to relevant personnel.
Conduct a short exercise at least once a year and after major changes to systems or operations. An exercise does not need to stop the working day. A scenario can be set up where email is inaccessible or an accounting system fails, and discuss what happens in the first 30 minutes. Unclear roles, old contacts, and unrealistic assumptions will quickly become apparent.
Update the plan after every incident or test. Operations change, new software vendors are introduced, and people change roles. An emergency plan that was correct two years ago may be dangerously outdated today. Regular review costs little compared to the cost of prolonged operational downtime.
Companies do not have to solve this alone. At nexIT, we help customers connect daily system management, security defences, backups, and recovery processes so that responsibility is clear when it matters most. The best time to find weaknesses in an emergency plan is when operations are calm and everyone has room to fix them.